Streaming tokens to the browser
Streaming tokens to the browser
A three-hundred-token answer takes several seconds to generate. If Relay waits for the whole thing, the customer stares at a spinner for the whole time; if Relay forwards each token as it arrives, the first words appear in well under a second and the rest fills in as fast as the model writes. Nothing about the total time changes. What changes is when the user learns the system is working, and that is most of what "fast" means in a chat interface.
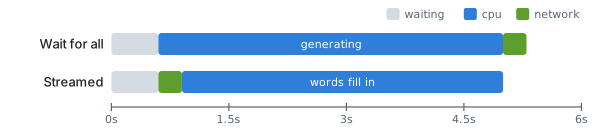
The pipeline has three stages: the provider streams events to your process, an async generator turns those events into server-sent events, and StreamingResponse pushes them to the browser. Lesson 07.02 built the SSE side; this lesson puts a model at the front of it.
Continue reading
Pro unlocks every video lesson, the full notes and runnable code across the Python with AI course, from the language itself to agents, MCP, Langfuse and deployment.