What inference engineering is
Training produces a file. For an open model such as Qwen/Qwen3-30B-A3B-Instruct-2507, that file is 30.5 billion parameters at two bytes each, about 61 GB of numbers, plus a small config.json that says how to arrange them. The file does nothing on its own. Inference engineering is the work of turning it into a service: something that accepts a prompt over the network, runs the model on a GPU, streams tokens back fast enough that a person keeps reading, costs little enough that the product makes money, and keeps doing all of that when a thousand people arrive at once or a GPU fails in the middle of the night.
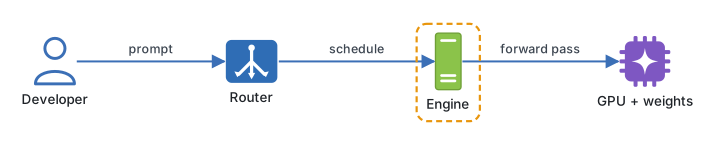
Three quantities pull against each other in almost every decision you will make: latency (how long a user waits), cost (what each request costs you), and quality (whether the answers are good enough for the product). Most techniques in this course buy one of them with a little of another. A few, the ones worth the most attention, move one without touching the others. The job is knowing which is which, and proving it with measurements.
Why serving is a discipline of its own
Training a model is a large bill paid once. Serving it is a bill that grows with every user, every day, for as long as the product exists. It also has a person waiting at the other end of each request, which training never does.
This course follows one product throughout. Kite is an AI coding assistant with four model workloads: chat about a repository, tab completion in the editor, nightly embedding of changed files, and later a voice mode. Take the chat workload and put rough numbers on a single day. Assume 10,000 active developers who each ask 20 questions, and a typical request that carries 6,000 tokens (a 5,700-token system prompt and retrieved files, then a 300-token question) and gets back a 400-token answer.
| Quantity | Arithmetic | Result |
|---|---|---|
| Requests per day | 10,000 × 20 | 200,000 |
| Input tokens per day | 200,000 × 6,000 | 1.2 billion |
| Output tokens per day | 200,000 × 400 | 80 million |
| Share of tokens that are input | 1,200 ÷ (1,200 + 80) | ≈ 94% |
| Average arrival rate | 200,000 ÷ 86,400 s | ≈ 2.3 requests/s |
| Rate if most arrive in an 8-hour workday | 200,000 ÷ 28,800 s | ≈ 6.9 requests/s |
| Busiest morning hour, about a fifth of the day | 43,200 ÷ 3,600 s | ≈ 12 requests/s |
Two lessons fall out of this table before any GPU is involved. First, nearly all the tokens Kite processes are prompt, not answer, so how the model reads a prompt, and whether it can avoid rereading the same 5,700-token prefix 200,000 times, will matter more than a first guess suggests. Second, traffic is not flat. A deployment sized for the daily average of 2.3 requests per second would fall over in the busiest hour, at about five times that rate.
The model choice already reflects an inference decision. A dense transformer costs about 2 × (parameter count) floating-point operations per token. Qwen3-30B-A3B is a mixture-of-experts model with only 3.3 billion parameters active per token, so each token costs about 2 × 3.3 billion = 6.6 billion operations instead of the 61 billion a dense 30.5B model would need. That is roughly nine times less compute per token, while every one of the 61 GB of weights still has to sit in GPU memory.
The layers you will work in
An inference request passes through several layers, and a problem that shows up in one often starts in another.
| Layer | The question it answers | Where in this course |
|---|---|---|
| Use case | What latency, cost, and quality do we need? | Module 01 |
| Model | What runs per token, and how much memory does it take? | Module 02 |
| Hardware | Which GPU, how many, connected how? | Module 03 |
| Software | Which kernels and engine: vLLM, SGLang, TensorRT-LLM? | Module 04 |
| Techniques | Quantization, speculative decoding, caching, parallelism | Modules 05 and 06 |
| Other modalities | Vision, embeddings, speech, image and video | Module 07 |
| Production | Containers, autoscaling, regions, deploys, monitoring | Module 08 |
Consider a single complaint: "Kite chat takes two seconds to start answering." The cause might be requests waiting in a queue because autoscaling reacted too slowly (production), a prompt that grew to 30,000 tokens after a retrieval change (use case), a prefix cache that stopped hitting because someone put the current time at the top of the system prompt (techniques), or a GPU that is too small for the batch it is running (hardware). The symptom is the same in each case. The fix is completely different. An inference engineer's first skill is breaking a slow request into its parts and measuring each one.
Engineering note. Before changing anything, write the three targets down as numbers: a P90 time to first token, a cost per thousand requests, and a pass rate on an evaluation set you trust. A change measured against only one of them is a guess about the other two.
Where it goes wrong
- Optimizing the wrong number. A team spends a month cutting the time between streamed tokens while users complain about the wait before the first one, which was dominated by queueing.
- Reporting averages. A mean latency of 400 ms can hide one request in fifty taking six seconds. Users remember the six seconds. Report P50, P90, and P99.
- Silent quality loss. A cheaper number format or a smaller model passes a public benchmark and then fails on the repositories your customers actually have. Only your own eval set catches this.
- Sizing for the average. Capacity planned for 2.3 requests per second meets 12 at ten in the morning, and the queue grows until requests time out.
- Memory that grows with the request. A model that fits comfortably with 2,000-token prompts runs out of GPU memory at 32,000 tokens, because the cache of intermediate results grows with every token of context.
Try it
Pick a product you work on, or use Kite. In fifteen minutes, estimate its daily requests, typical input and output tokens per request, the share of tokens that are input, and the peak arrival rate if traffic concentrates into working hours. Write down which of latency, cost, and quality you believe matters most for it, and what number would count as failure. Keep the sheet; later lessons will ask you to revise it.
Next, the life of an inference request follows one Kite chat question from the keystroke to the last streamed token.
Continue with the complete track
Keep your progress and unlock the surrounding lessons, exercises, and complete learning path.
Unlock the complete track