Compute-bound or memory-bound
Compute-bound or memory-bound
Every forward pass moves numbers between memory and the processor and does arithmetic on them. Whichever is slower sets the speed. When the chip spends most of its time waiting for bytes to arrive, the work is memory-bound, and a processor with more arithmetic power changes nothing. When the bytes are already there and the chip is busy multiplying, the work is compute-bound, and faster memory changes nothing.
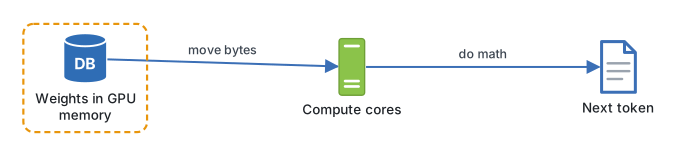
LLM inference contains one of each. Prefill pushes the whole prompt through the model in parallel: thousands of tokens of arithmetic for one read of the weights, so it is compute-bound. Decode produces one token per forward pass and has to read every weight again to do it, so at small batch sizes it is memory-bound. Which GPU to rent, how large a batch to run, and whether to quantize all follow from telling them apart.
Continue reading
Pro unlocks every video lesson, the full notes, worked sizing and cost calculations, and runnable configs across the Inference Engineering course, from GPUs and kernels to quantization, speculative decoding, disaggregation and production autoscaling.