Inside a datacenter GPU
Inside a datacenter GPU
From the outside, a datacenter GPU is a card with a memory number printed on the price list: 80 GB, 141 GB, 180 GB. Inside, it is a layered system. A compute die with thousands of simple cores sits on a package next to stacks of high-bandwidth memory (HBM). A small amount of even faster memory lives on the die itself. The whole card connects to a host CPU and its much larger system memory over PCIe, and to other GPUs over NVLink.
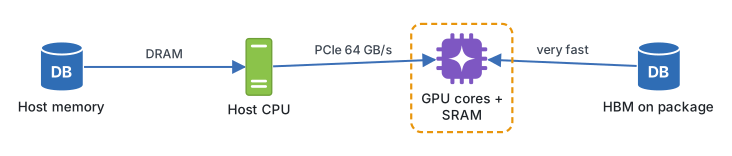
Each layer is larger and slower than the one closer to the cores. That shape explains most of what you will see in production: why models must fit in GPU memory, why a host with a slow CPU can starve an expensive card, and why moving some data off the card is fine while moving other data off it is ruinous.
Continue reading
Pro unlocks every video lesson, the full notes, worked sizing and cost calculations, and runnable configs across the Inference Engineering course, from GPUs and kernels to quantization, speculative decoding, disaggregation and production autoscaling.