Tokens, chat templates, and sampling
Tokens, chat templates, and sampling
A model never sees text. On the way in, a tokenizer cuts a string into pieces from a fixed vocabulary and replaces each piece with an integer. On the way out, the model produces one score, called a logit, for every entry in that vocabulary, and a sampler turns those scores into a single chosen id, which is turned back into text. Everything the serving engine counts, bills and caches is measured in those ids.
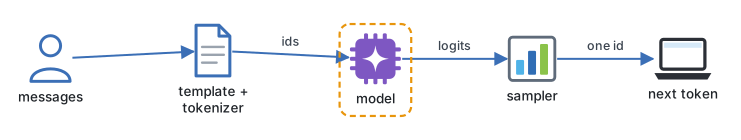
Between the two sits the chat template: the exact text, special markers included, that wraps a list of messages into one string. It is easy to treat as plumbing. It is actually part of the prompt, and getting it wrong breaks a model in ways that look like the model being bad.
Continue reading
Pro unlocks every video lesson, the full notes, worked sizing and cost calculations, and runnable configs across the Inference Engineering course, from GPUs and kernels to quantization, speculative decoding, disaggregation and production autoscaling.