Transformer blocks and attention
Transformer blocks and attention
A decoder-only transformer is one block copied many times. Llama 3.1 8B stacks 32 of them, Qwen3-30B-A3B stacks 48. Each block does two things to every token's vector. Attention lets the token gather information from the tokens before it. The MLP then transforms each token on its own. Both results are added back onto the vector that came in, so information flows straight down the stack and each block only adds a correction.
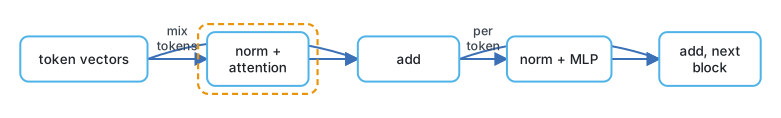
In code, the whole block is four lines: normalize, attend, add; normalize, MLP, add. The MLP and the projections are the matrix multiplications you already counted. Attention is different, because it is the one operation whose work depends on how many tokens are in the context, and that is where long prompts get expensive.
Continue reading
Pro unlocks every video lesson, the full notes, worked sizing and cost calculations, and runnable configs across the Inference Engineering course, from GPUs and kernels to quantization, speculative decoding, disaggregation and production autoscaling.