Choosing a GPU for a workload
Choosing a GPU for a workload
A GPU choice is three questions asked in a fixed order. First, does the model fit, with room for the KV cache your traffic needs? Second, is the workload memory-bound or compute-bound, which tells you whether to pay for bandwidth or for arithmetic? Third, what does a million tokens cost on each candidate at the latency you promised? The hourly price on a provider's page answers none of these by itself.
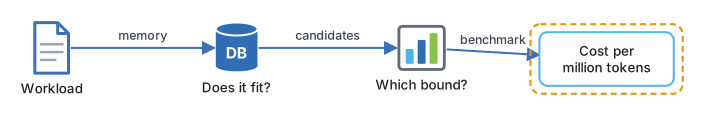
Answering the first question needs only arithmetic and a config.json. The second comes from the previous lessons. The third needs a benchmark, but the formula that turns a benchmark into a decision is one line.
Continue reading
Pro unlocks every video lesson, the full notes, worked sizing and cost calculations, and runnable configs across the Inference Engineering course, from GPUs and kernels to quantization, speculative decoding, disaggregation and production autoscaling.