Faster image and video generation
Faster image and video generation
An image model's run time comes down to one multiplication: the number of denoiser passes times the cost of one pass. The text encoder runs once and the VAE decoder runs once. The diffusion transformer in between runs again and again, and every one of those runs is compute-bound work over the whole latent. That means the tricks that help LLM decode, such as bigger batches and more memory bandwidth, matter much less here. What matters is how many passes you make and how expensive each one is.
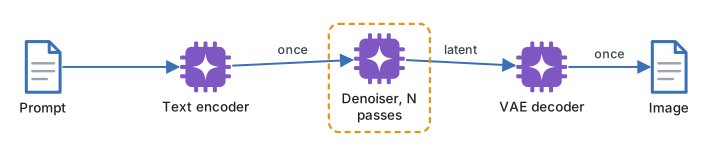
So there are two groups of levers. Cutting passes: fewer steps, and not paying twice per step for guidance. Cheapening each pass: compiling, quantizing, and for video, splitting a very long token sequence across a node of GPUs.
Continue reading
Pro unlocks every video lesson, the full notes, worked sizing and cost calculations, and runnable configs across the Inference Engineering course, from GPUs and kernels to quantization, speculative decoding, disaggregation and production autoscaling.